Kubernetes-Native ML Platforms Need Reconciliation Across the Model Lifecycle
Kubernetes can run ML workloads, but a declarative control plane is what makes training, evaluation, deployment and recovery manageable.
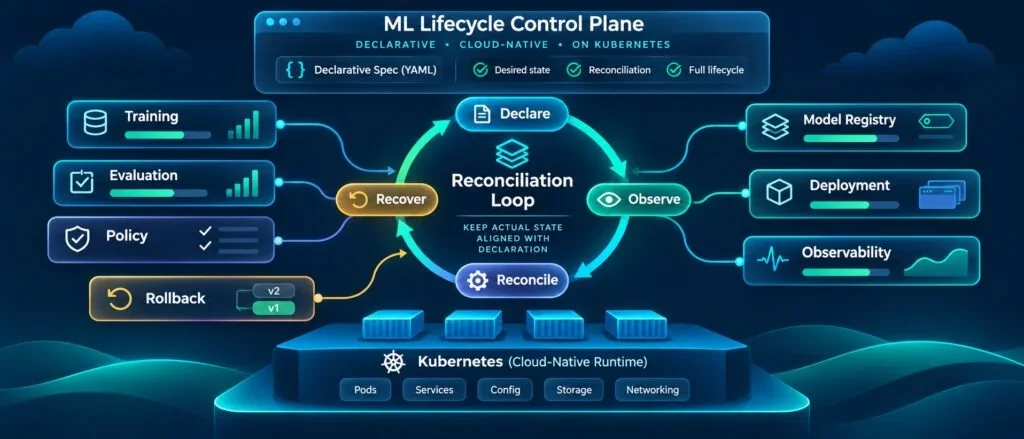
Kubernetes can schedule model training, host inference services and allocate accelerators. That solves important infrastructure problems, but it doesn’t automatically make an ML platform Kubernetes-native. The deeper change comes when teams manage the model lifecycle through declarative state: users specify what they want, controllers observe what exists, and the platform works to close the gap.

Without that model, training, evaluation, model registration, deployment and rollback can remain split across separate APIs, databases and custom scripts. Kubernetes runs the compute while bespoke glue coordinates the work. That arrangement can function, but it makes failures harder to diagnose and recovery harder to repeat.
As Vara Bonthu described in a CNCF article about AI workloads moving to Kubernetes, the shift of training and inference onto the platform is already underway. The next step is to apply Kubernetes’ operating model to the lifecycle around those workloads.
Model work is a continuing process
A production model is connected to the data, code and parameters that produced it. Evaluations add results that inform whether a model is ready to use. A deployment, in turn, needs to identify the model version it serves and report its health, rollout progress and traffic allocation.
These connections need to persist across infrastructure failures, process restarts and changes in the teams operating the system. That makes the platform’s job less like running a sequence of isolated batch tasks and more like managing a state machine whose parts change over time. The platform needs to preserve relationships and make the current state visible.
Reconciliation puts intent in control
The reconciliation loop provides a way to do that. A user or automation system declares a desired state; a controller checks the live state, takes action when the two differ and reports progress. It repeats those checks, so a temporary interruption doesn’t have to become a manual recovery procedure.
For example, a team might declare that model version 42 should serve 10% of production traffic and remain healthy. If the version currently receives no traffic, a controller can create or update the runtime resources needed for a canary rollout, then assess health signals as traffic shifts. Status can show whether progress is waiting on capacity, blocked by a check or interrupted by an unhealthy model.
When a rollout spans clusters, the control plane can advance it gradually and stop when problems appear, limiting how widely a failure spreads. Custom resources and controllers let platform teams represent concepts such as training runs, evaluations and deployments in this model. Users can express intent in terms of their ML workflow while controllers handle the implementation details.
Make lifecycle state visible
Representing durable lifecycle concepts as Kubernetes resources creates an observable map of how artifacts relate. A training run can point to its inputs and produce a model resource with lineage and evaluation results. A deployment can refer to a particular model version and expose health and traffic status.
That structure affects day-to-day operations. Controllers can retry after transient failures, treating recovery as ordinary work. Consistent status conditions can show whether each resource is pending, progressing, ready, degraded or blocked. Metrics and logs can be tied to the lifecycle object responsible for a problem, giving operators more context than a message that only reports a failed pod.
It also creates a useful boundary for checks. Admission controls can enforce fast, predictable requirements such as resource limits and data restrictions when a request enters the system. Controllers can coordinate longer-running evaluation and approval steps. Versioned, typed APIs then give web interfaces, command-line tools, controllers and AI agents a shared contract to build on.
Connect execution tools through a control plane
A lifecycle control plane doesn’t need to replace training, data processing or inference engines. Those specialized systems do the heavy work. The control plane describes intent, relationships, checks and status; adapters translate that intent into resources each execution engine understands; results flow back into the shared lifecycle model.
This separation gives users a consistent way to operate different workloads without forcing every workload into the same implementation. It also lets platform teams change an execution engine without redesigning the whole user experience.
There’s a boundary to maintain, though. Kubernetes resources should capture durable intent that users or automation need to manage, such as a model deployment, rather than every temporary operation. Large model files, logs, traces and detailed evaluation results belong in stores suited to those artifacts. Lifecycle resources can keep references and concise status.
A proposed resource is a good fit when it represents meaningful intent, outlives a single process, needs to be tracked by people or automation, benefits from continuous reconciliation and has an API stable enough to serve as a lasting contract.
Keep the contracts durable as AI changes
Paul Zimmerman points to his experience with Uber’s ML platform, Michelangelo AI, whose modular control plane has been released as an open-source project. The durable abstraction, in his account, is the lifecycle contract connecting training runs, models, evaluations and deployments—not a particular training engine, serving runtime or workflow system. Those tools change; the relationships and operational questions remain.
That distinction also applies as platforms add generative and agentic AI. Prompts, tools, policies, benchmark suites and traces extend the set of artifacts a team must track. Teams still need to know what a system was asked to do, which versions and inputs it used, what happened, whether it met evaluation requirements and whether the result can be reproduced, promoted or rolled back.
There’s no need for one universal MLOps API: workloads differ too much for a single rigid design. Shared conventions could still help teams carry lifecycle relationships, status, workload definitions, identity boundaries, evaluation flows and resource observability across runtimes, clusters, clouds and accelerator types.
Kubernetes provides a common foundation for running AI workloads. A platform earns the “native” label when its users can also declare and inspect the lifecycle, and its controllers can reconcile that intent through failure and change. That’s the practical test to watch as ML platforms mature.


